Pipelines and streamlets
A pipeline is a graph of streamlets connected by Kafka topics. Each streamlet has named, typed inlets and outlets, together called its ports. A blueprint says which streamlets a pipeline uses and which topic connects which ports. The platform checks the blueprint before anything runs.
shop.cart-events.v1 ──► router ──valid──► cart.valid-carts
                               └─review─► cart.review-carts
Where ankka ends and ankka-flow begins
An ankka consumer already reads a Kafka topic, and can produce to one. A single service reacting to a topic is an ankka consumer and should stay one.
ankka-flow is the layer above. Reach for it when a design needs several of these:
- a graph of stages whose contracts are checked against each other before anything runs;
- several typed outlets per stage, with fan-out;
- topics the platform creates and owns;
- per-key ordering preserved through a chain of stages;
- a pipeline rebuilt from the start of its inputs;
- lag attributed to each stage;
- sinks that batch and commit only after writing somewhere else.
If a design needs none of those, it is not a flow.
A streamlet
A streamlet is code, in any language, in its own container image. It declares its ports, each with a contract, and its typed parameters, and implements one function: take a batch of records from an inlet and emit records to outlets. The image holds only that code. Everything to do with Kafka belongs to the sidecar the platform runs beside it.
The streamlet's SDK writes a descriptor from its declaration when the streamlet is built. The
descriptor is the streamlet as the platform sees it: its name, ports, contracts and parameters. A
blueprint is checked against descriptors, never against code, so checking a pipeline needs no image,
no network and no language runtime. The Python SDK writes one with
uv run descriptor; the format is on Descriptor.
A blueprint gives each streamlet a name of its own and names the descriptor it runs, so one streamlet can appear twice in a pipeline under two names.
Topics connect ports
A topic in a blueprint lists the outlets that produce to it and the inlets that consume from it. Every inlet is connected to exactly one topic; an outlet is connected to at most one, and an unconnected outlet is allowed. The outlets and inlets on one topic must carry equal contracts.
A topic is either managed, created and owned by the pipeline, or unmanaged, owned by something else and only read. Topics and Kafka clusters explains both, how a topic's Kafka name is chosen, and where its connection settings come from.
From blueprint to cluster
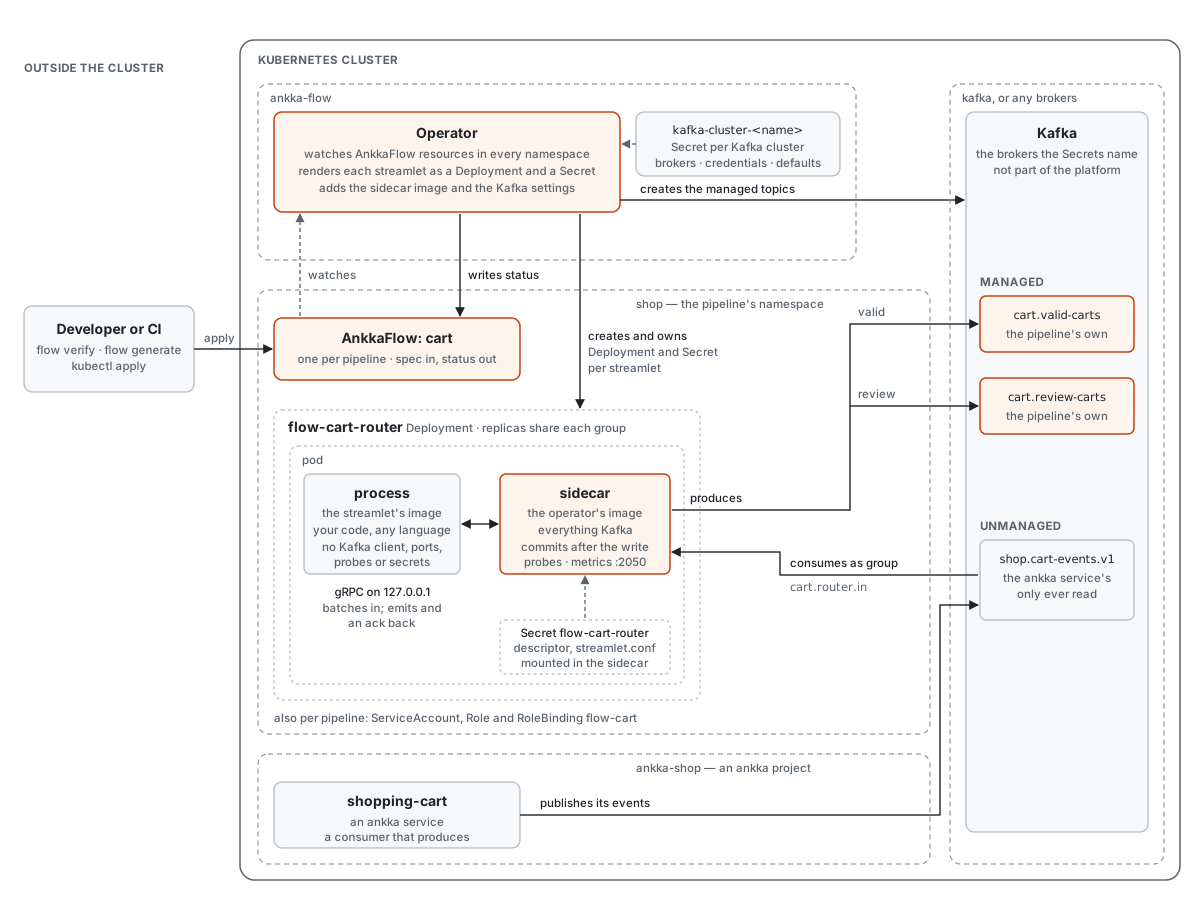
- The SDK writes each streamlet's descriptor.
flow verifychecks the blueprint against the descriptors and reports every problem in one pass.flow generatewrites theAnkkaFlowresource: every descriptor, image, binding and topic, with deploy-time configuration already merged in.- The operator creates the managed topics and runs each streamlet as a Deployment whose pods hold the streamlet's container and the sidecar.
Write a blueprint walks through steps 1 and 2; Deploy a pipeline covers 3 and 4.